 developer workflows
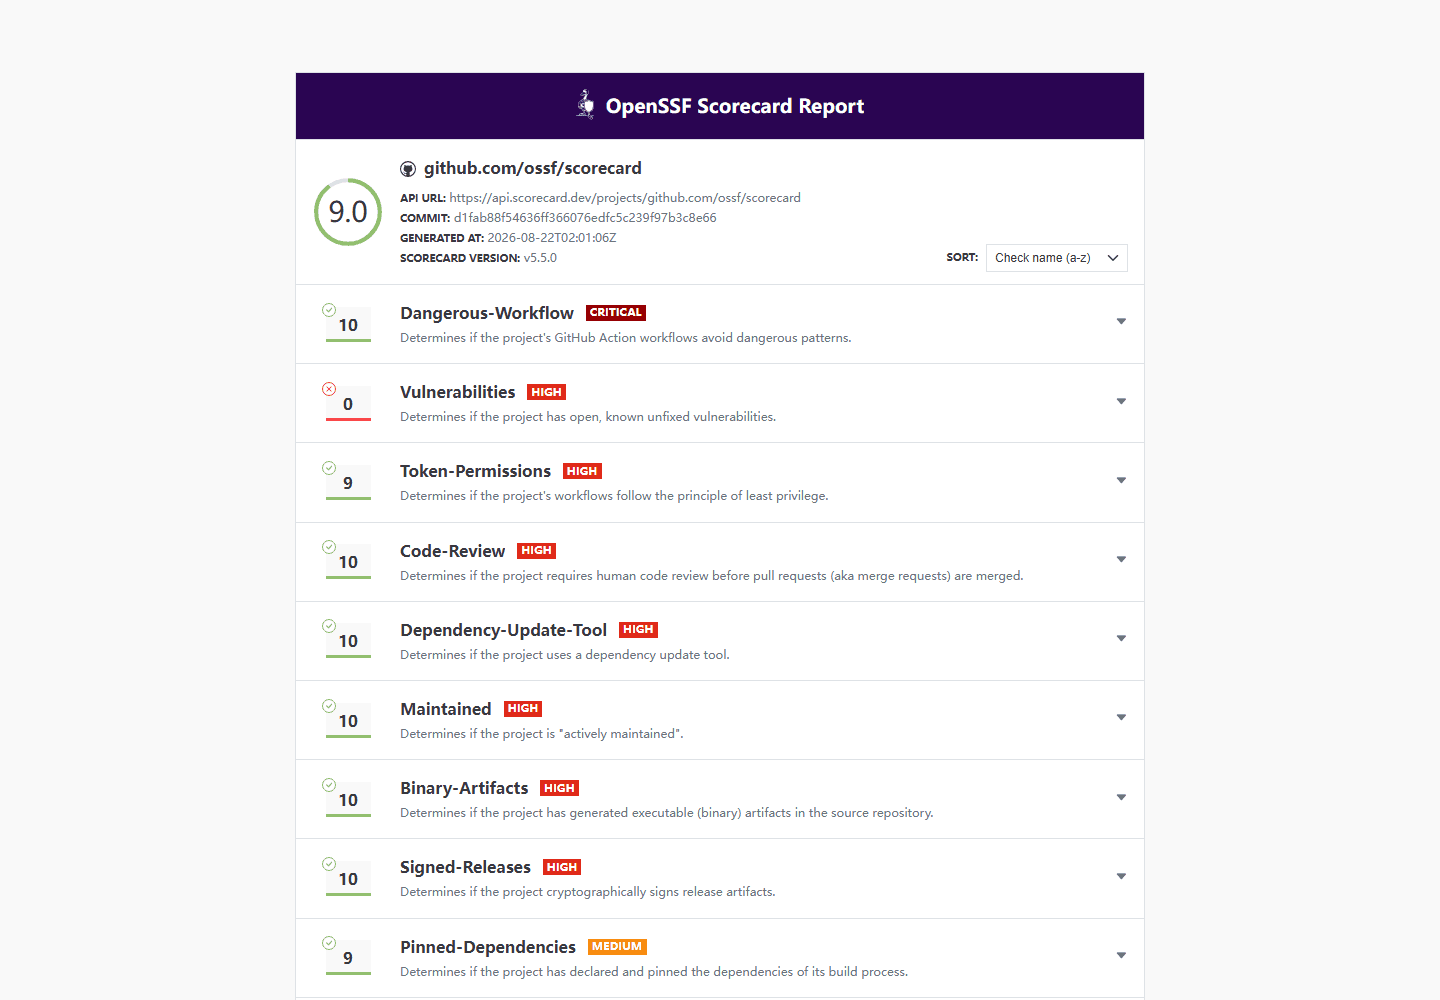
ossf/scorecard: A Fabricated Pin Still Scored 10 in Our Local Test
Inspect seven dated Scorecard fixtures, including a fabricated commit pin that still scored 10, and separate scanner signals from workflow execution.
Read the guide AI ops and monitoring
GitHub Actions GITHUB_TOKEN Audit: Reduce Workflow Permissions Before a Third-Party Action Runs
Audit GitHub Actions token permissions job by job, pin third-party actions, and test the workflow after removing write access it does not need.
Read the guide agent tools and workflows
modelcontextprotocol/servers: Audit an MCP Server Before Giving It Files, Tokens, or Network Access
Audit an MCP server’s tools, credentials, file reach, and network side effects before connecting it to an AI client or production account.
Read the guide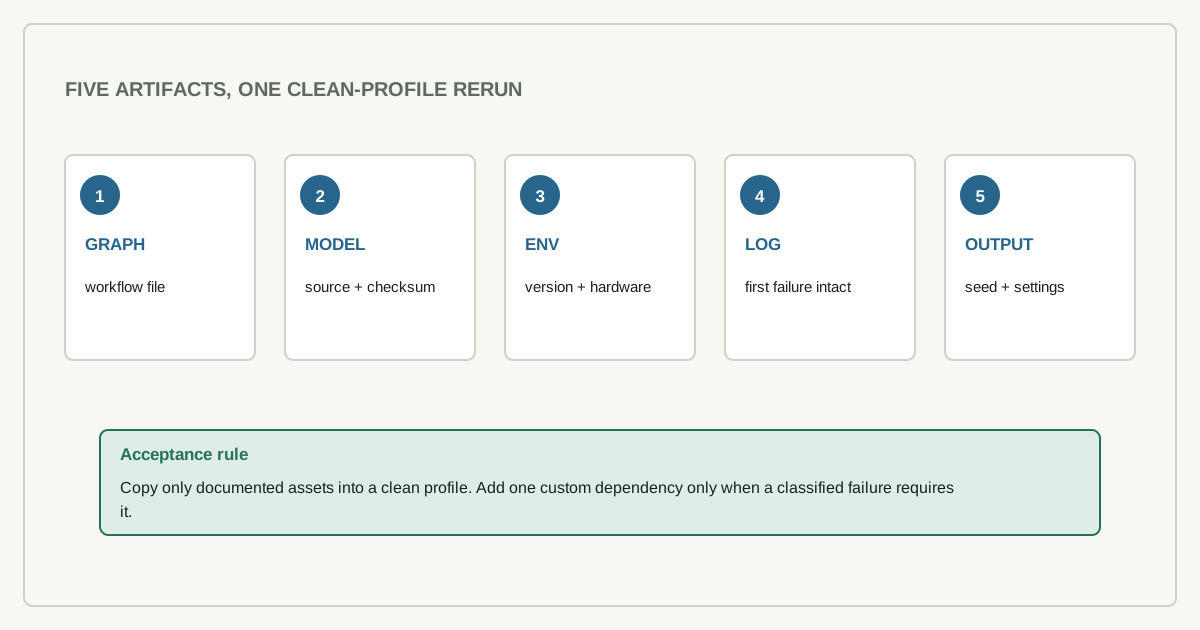 GitHub AI project watchlist
Comfy-Org/ComfyUI: Test Workflow Portability Before Installing Custom Nodes
Test a ComfyUI workflow on a clean profile, record models and dependencies, and identify custom-node lock-in before a graph becomes hard to reproduce.
Read the guide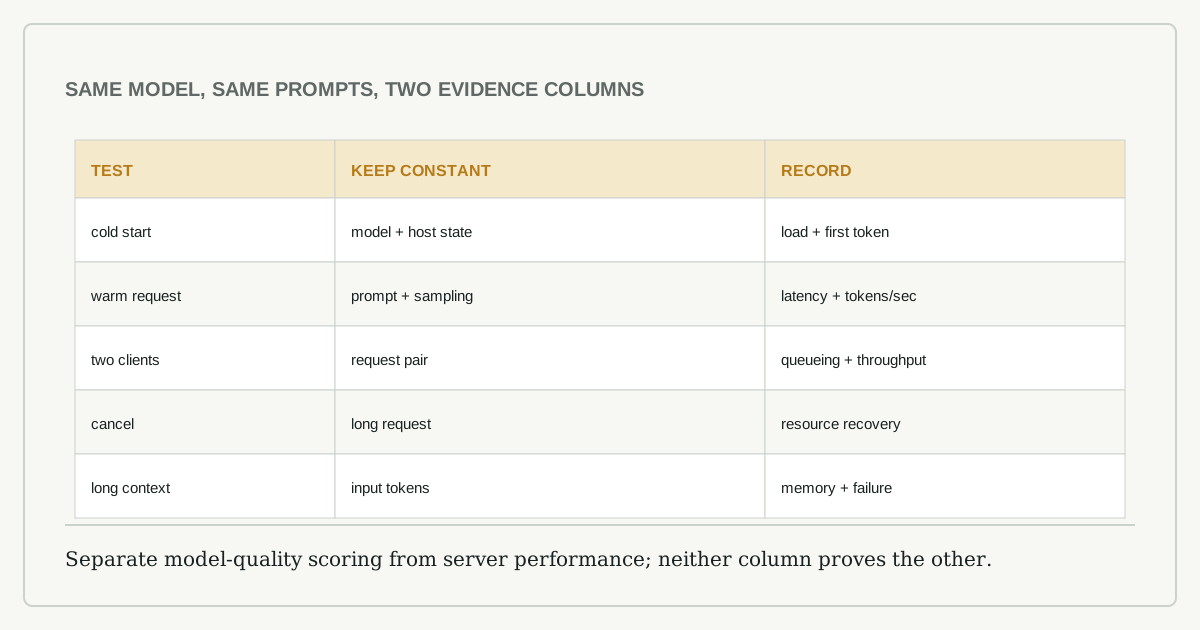 Open-source AI comparisons
ollama/ollama vs ggml-org/llama.cpp: Choose a Local Model Server With a Measured Workload
Compare Ollama and llama.cpp using one pinned model, repeatable prompts, latency, memory, concurrency, API needs, and recovery behavior.
Read the guide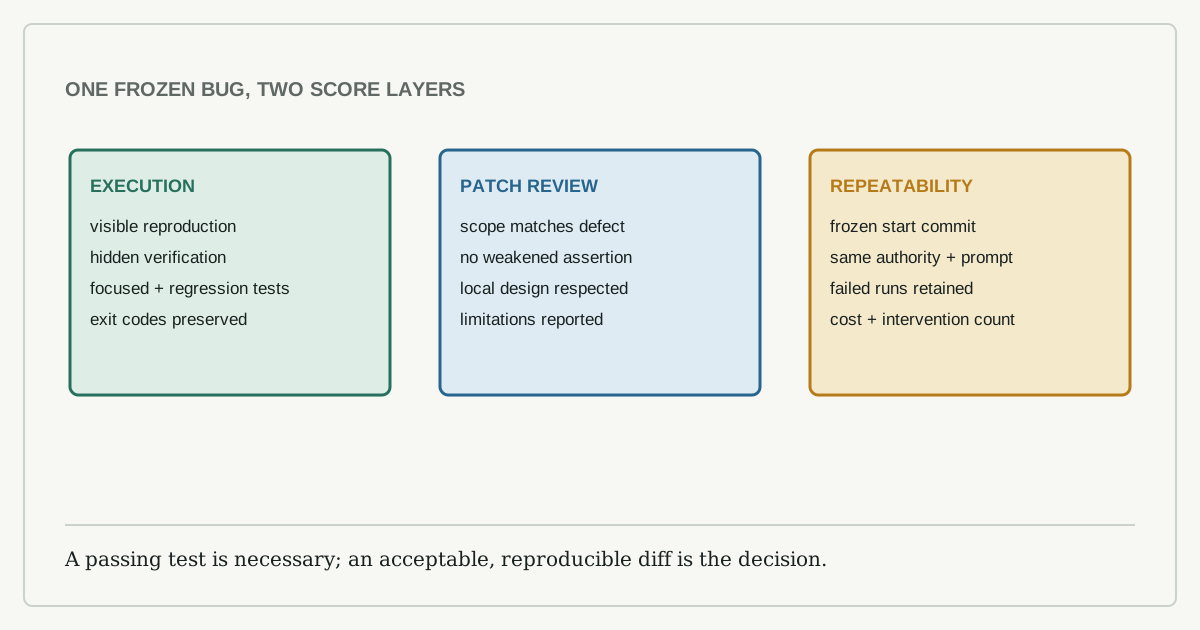 model release analysis
Evaluate a Coding Agent With One Bug, One Test, and a Diff You Can Review
Evaluate a coding agent on one real bug with a frozen repository, hidden test, clean-diff rubric, cost record, and reproducible review artifacts.
Read the guide developer workflows
How to Read a GitHub Project's Health in 10 Minutes Before You Depend On It
Review an open-source dependency in ten minutes: releases, issue triage, maintainer concentration, public security evidence, and license fit.
Read the guide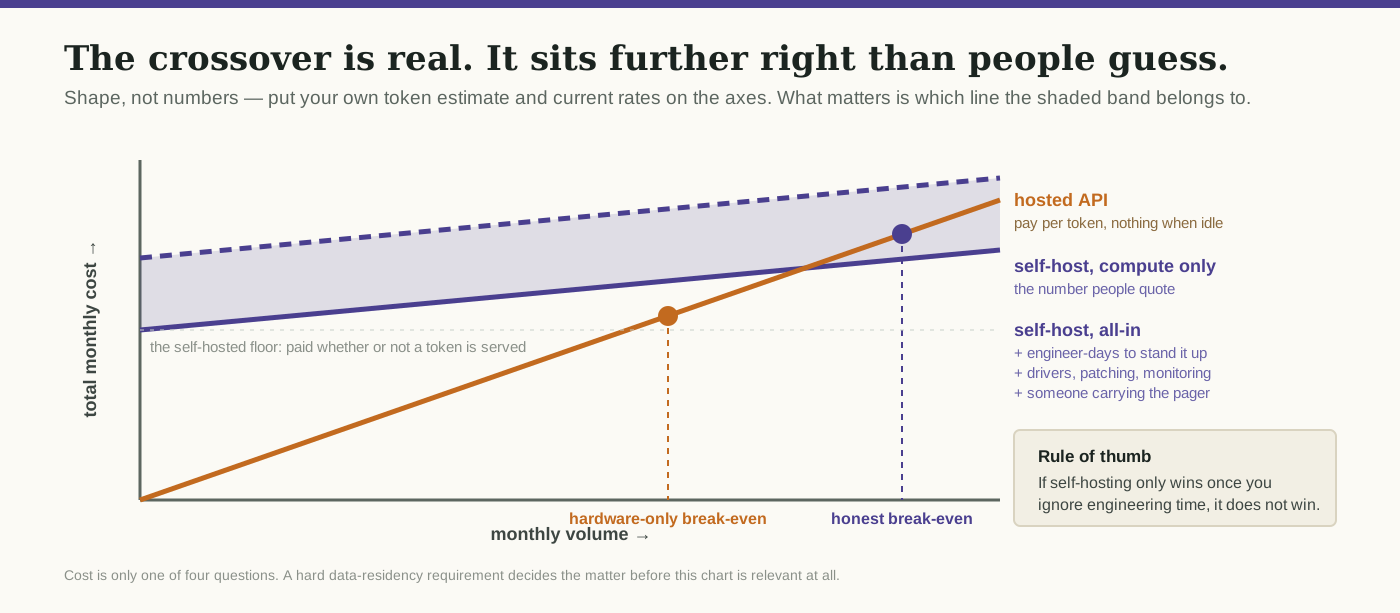 Local models and LLM infrastructure
Self-Host an Open Model or Call an API? A Cost-and-Risk Decision Tree
A practical decision tree for small teams choosing between self-hosting an open model and calling a hosted API: privacy, cost curve, latency, and ops burden.
Read the guide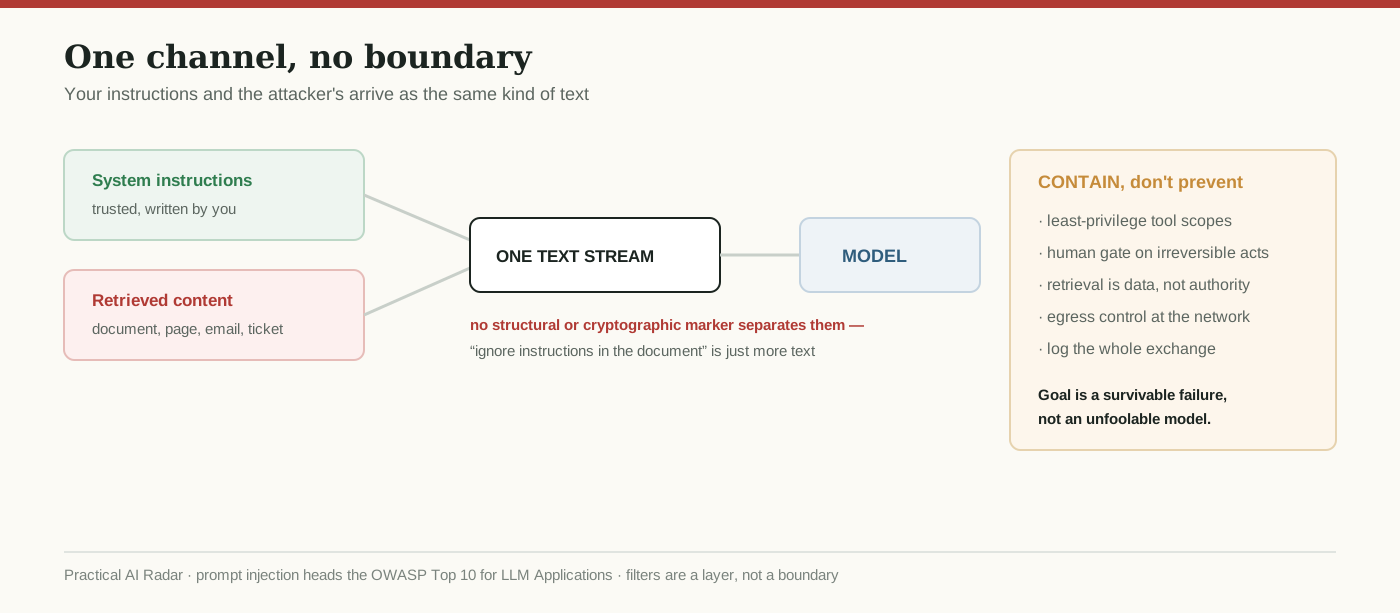 agent tools and workflows
Prompt Injection: Why Instructions Alone Are Not a Security Boundary
Understand direct and indirect prompt injection, the limits of instruction hierarchy, and how tool permissions, approval checks, and egress controls reduce risk.
Read the guide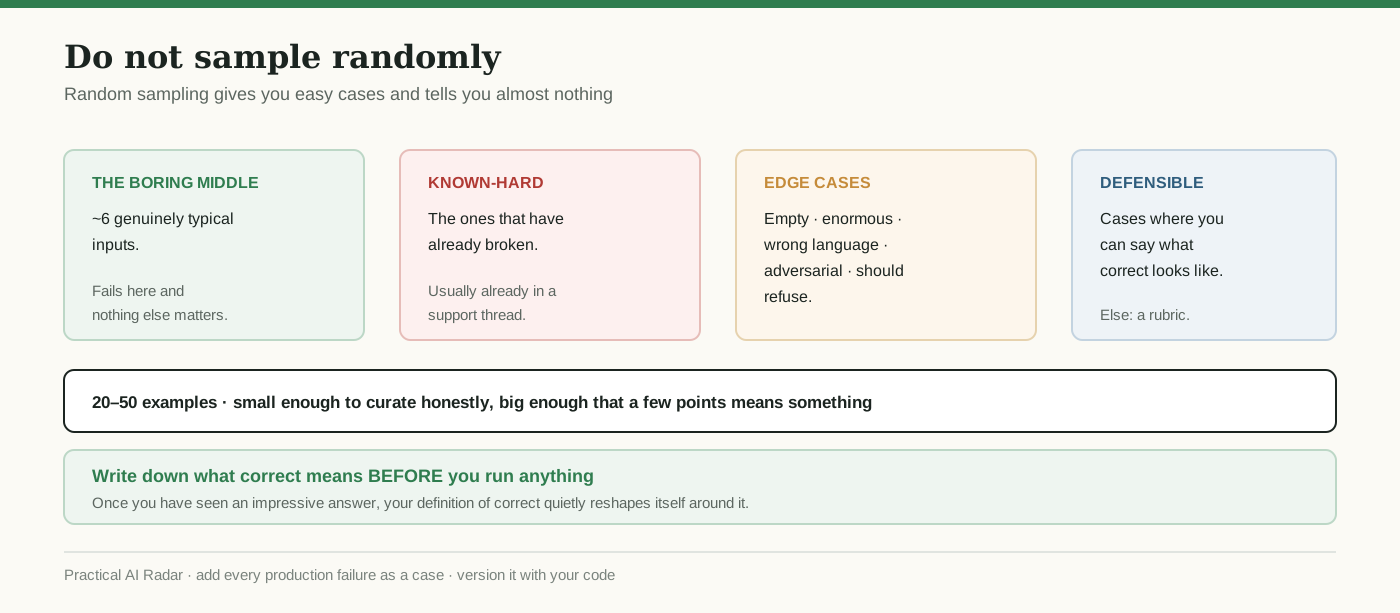 model release analysis
Build The Eval First. Then Argue About Models
Public benchmarks measure a different task than yours. How to build a small evaluation set that makes model choice, prompt changes and upgrades decidable.
Read the guide AI ops and monitoring
HTTP 200, Then Timeout: What a Useful Model-Call Log Must Distinguish
Trace a 200 response that times out while reading its body, inspect limited logging fields, and preserve unknown usage without collecting every payload.
Read the guide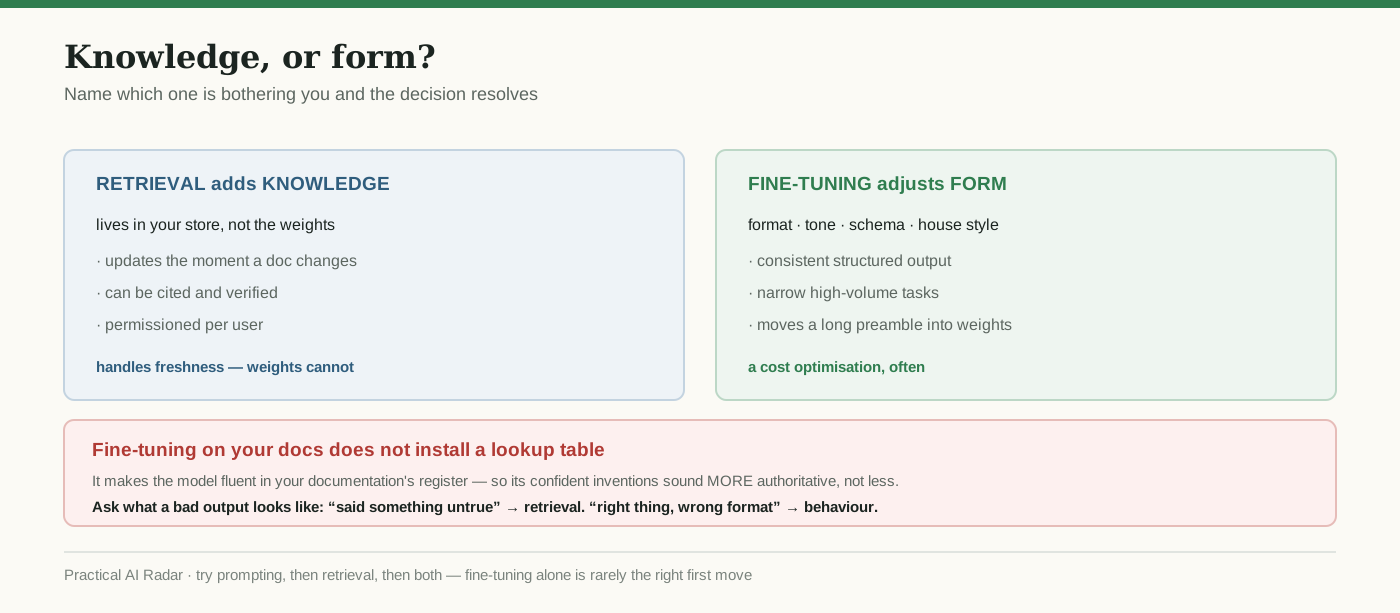 model release analysis
RAG or Fine-Tuning: Diagnose the Failure Before Choosing
Choose retrieval, fine-tuning, or both by inspecting failures: source freshness, access, answer support, task behaviour, and held-out evaluation results.
Read the guide